
AI-INFRA 100: GPU Clusters Break the Datacenter Playbook
 Summarize with AI
 Claude
 ChatGPT
 Gemini
 Perplexity
 Grok
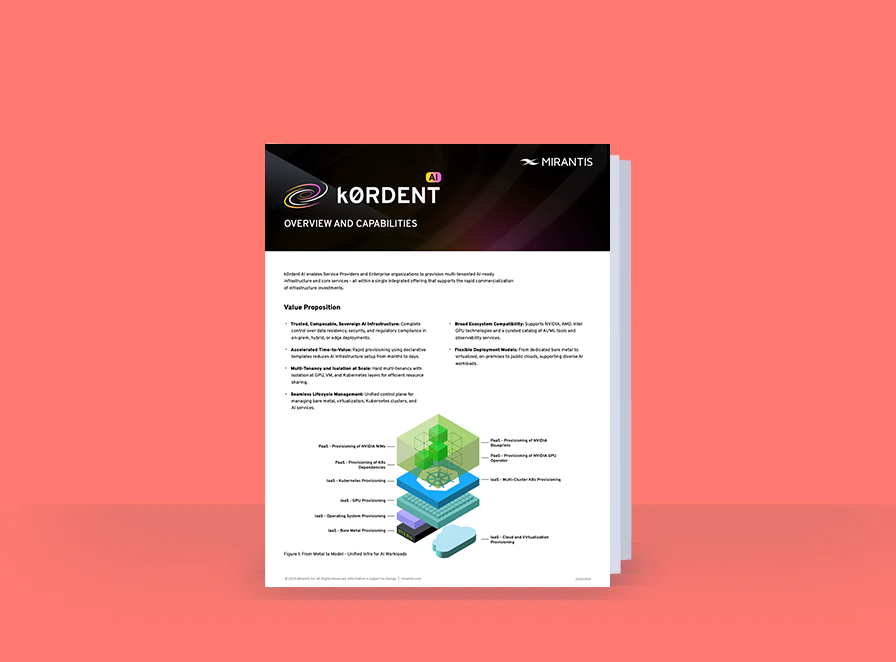
Monetize GPU Infrastructure with Mirantis k0rdent AI
15 years of infrastructure expertise, now in a GPU PaaS that makes your AI hardware productive the day it lands.
PUT YOUR GPUS TO WORK
You have managed servers, switches, and VMs for years. You are good at it. Now you have been asked to stand up a GPU cluster with DPUs and Redfish automation, and the uncomfortable part is not that the work is harder. It is that you cannot yet see the shape of what you do not know, in an environment where a mistake becomes something you have to diagnose in production.
AI-INFRA 100: GPU Cluster Infrastructure is built for that position. Four standalone modules covering the full stack, from architecture vocabulary to zero-touch provisioning.
Why the conventional playbook does not transfer
Conventional datacenter infrastructure tolerates packet loss. TCP retransmits, an application retries, and a user waits an extra moment. GPU clusters do not work that way. A distributed training job synchronizes across nodes, and a single dropped packet can stall every GPU in the collective. The economics of idle accelerators make that expensive fast.
Similar reversals run through the whole stack. Firmware becomes a first-class operational concern rather than something you touch during a hardware refresh. The network fabric requires lossless configuration you never needed before. Provisioning has to be repeatable across racks, not comfortable at the scale of a handful of hosts. The individual skills are familiar. The assumptions underneath them are not.
Who this is for
Infrastructure engineers taking on GPU cluster work for the first time, who want the map before the outage rather than after it.
Solutions and pre-sales roles who need to hold a credible technical conversation about GPU topology, RDMA fabric, and cluster automation without being the person implementing it. The Foundation module is built for exactly this. Conceptual depth is a different requirement from hands-on capability, and Foundation delivers it without asking you to configure PFC yourself.
Prerequisites are practical rather than academic: Linux CLI, TCP/IP networking basics, server hardware fundamentals, BMC/IPMI experience, and basic shell scripting. If BMC and IPMI are unfamiliar, start there before taking the course.
The modules
Foundation: AI Infrastructure Concepts & Vocabulary
A full stack walkthrough and architecture overview, plus the terminology everything else depends on: NVLink, HBM3e, DPU, RoCE v2, Redfish, UFM. Why AI infrastructure breaks the conventional datacenter playbook.
This is the recommended starting point for everyone, including people who intend to take only one module. Terminology is the thing that makes the other three legible, and it is also what lets you follow a vendor conversation without nodding at words you cannot define.
Redfish: BMC API, Firmware & Hardware Monitoring
Redfish for inventory, firmware updates, and GPU health, including multi-vendor BMC unification across Dell iDRAC, HPE iLO, Lenovo XCC, and Supermicro. Scripting for scale.
The multi-vendor problem is the practical heart of this module. Every BMC vendor has its own interface and its own quirks, and clicking through four different web UIs does not survive contact with a real fleet. Lab included.
GPU Cluster Networking: RoCE v2, PFC/ECN & Fabric
Lossless fabric fundamentals, a RoCE v2 deep dive, DPU integration, and UFM for fabric observability. Why zero packet loss is non-negotiable for GPU workloads rather than a stretch goal.
If you have configured PFC and ECN before without being certain why the thresholds were set where they were, this module is the one that fills that in. Lab included.
Cluster Provisioning: Bare-Metal Management & k0rdent
k0rdent with Metal3/Ironic, plus GPU Operator and Network Operator deployment. An incremental deploy-and-validate methodology that holds up at scale.
The methodology matters as much as the tooling. Provisioning a rack and discovering at the end that something was wrong at the start is a specific and avoidable kind of expensive. Lab included.
Format
Each module stands alone and they can be taken in any order, though Foundation is the recommended starting point. Three of the four include hands-on labs. Reference materials are yours to keep.
AI-INFRA 100 can be scheduled for your team. If your interest is in building applications and agents on top of this infrastructure rather than running the infrastructure itself, look at AI-DEV 100: Agentic Workshop. The two tracks are independent, and neither is a prerequisite for the other.